Scanned PDF Pages to Text: How to OCR a Scanned Document
A scanned PDF looks like a document, but to a computer it is a stack of photographs. Each page is an image, and the file contains no text at all — you cannot search it, copy from it, or have a screen reader read it aloud. Converting a scanned PDF to text means running OCR on every page image inside it, and getting back a document you can actually use.
This guide explains how to convert scanned PDF pages to text: how to tell whether your PDF is scanned or real text, how to get the page images out, how to OCR them as a batch, and how to put the result together as a searchable document. The converter on the home page reads image files, so the first step is turning the PDF pages into images; the rest of this guide walks through that. For the general method, see how to convert an image to text; for single images, the JPG to text guide and PNG to text guide cover the formats.
Is Your PDF Scanned, or Real Text?
Not every PDF needs OCR. A PDF created by Word, or exported from a program, contains real text: you can select it, copy it, and search it. A scanned PDF contains only images of pages. Before you do anything else, find out which kind you have, because OCRing a PDF that already has text is a waste of time.
The test takes five seconds. Open the PDF, try to select a sentence with your mouse, and copy it. If you can select the text and paste it somewhere as words, the PDF has a real text layer and you do not need OCR at all — use the copy and paste. If you cannot select anything, or if selecting drags a rectangle around the whole page as if it were a picture, the PDF is scanned, and OCR is the way forward.
There is a third case: a PDF with a text layer that is wrong. Some PDFs were OCRed badly years ago, and the hidden text is full of errors, or the text is there but in the wrong order. If you select and copy text and it comes out as garbage, treat the PDF as scanned and re-OCR it from the page images. A fresh OCR pass with a modern engine is usually better than a text layer from a decade ago.
Getting the Page Images Out of the PDF
SnapText reads image files, not PDFs, so each page of the PDF has to become an image first. There are several ways to do this, and the right one depends on what software you have.
The easiest way is your PDF reader. In Adobe Acrobat Reader, open the PDF, go to File, then Export to, then Image, and choose PNG. Each page becomes a separate PNG file. In Preview on a Mac, open the PDF, select a page, and use File, then Export, to save it as a PNG or JPEG. In most browsers, you can open the PDF, zoom to the page, and take a screenshot — but that is slower and lower resolution than exporting, so use it only for a page or two.
If you have many pages, a command-line tool is faster. On Linux and macOS, pdftoppm (part of the Poppler tools) converts a whole PDF to images in one command, at whatever resolution you ask for: pdftoppm -png -r 300 document.pdf page produces one PNG per page at 300 dots per inch. On Windows, the same tool is available through the Poppler package, and there are free graphical tools that do the same thing. The important setting is the resolution: 300 DPI is the standard for OCR, and it is the resolution to ask for. Lower resolutions save space but cost accuracy; higher resolutions cost time and disk space for almost no gain.
One detail matters here: export as PNG, not JPG, when you have the choice. PNG is lossless, so the page image keeps every pixel exactly, and small text keeps its sharp edges. The PNG to text guide explains the difference in full. A JPG export at high quality is nearly as good, but PNG is the safer choice when you are converting a whole document and want the best result on every page.
How Many Pages, and How Long Will It Take?
A scanned PDF can be any length, from a two-page letter to a five-hundred-page book, and the plan matters. SnapText's free plan converts 10 pages a month, one image at a time. Starter converts 200 pages a month in batches of 50, and Pro converts 1,000 pages a month in batches of 200. A 200-page book is one Starter month, or a single Pro batch job spread over four uploads of 50 pages.
Time is the other constraint. A clean page takes a few seconds to OCR. A 200-page book takes roughly fifteen to thirty minutes of processing, depending on the pages. You do not have to watch it: leave an email address, and you will get a message when each batch finishes. The files are kept for 72 hours, so download the results the same day.
For very large documents — a whole archive, a multi-volume set — the practical approach is to work through the PDF in sections of 50 pages, one batch at a time, and to proofread by confidence as you go. The CSV report that comes with each batch lists every page with its mean confidence, so you can find the problem pages without reading all two hundred.
OCRing the Pages as a Batch
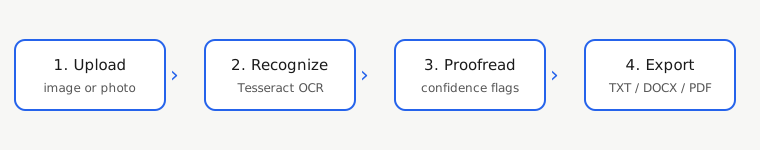
Once the pages are images, the conversion itself is straightforward. Upload the images in order — name them so the order is obvious, such as page-001.png through page-200.png, so the text files come back in the right sequence. Set the language to match the document. For a historical document, remember that the language may be older English, or a language with spelling that the modern language model does not expect; accuracy will be lower, and that is normal.
Choose your export formats before you start. For a scanned document you are converting to read, TXT is enough. For a document you are archiving, add searchable PDF: it keeps the original page image and adds a hidden text layer, so the filed copy is both the evidence and the searchable text. For a document you will edit, add DOCX. Exporting all three costs nothing extra, since SnapText counts one image as one page regardless of how many formats you download.
While the batch runs, the pages are processed in order. If a page fails — a blank page, a page that is only a photograph with no text, a corrupted image — the rest still complete, and the report tells you which page failed. Blank pages are common in scanned books: the inside of a cover, a divider page, a page that is only an illustration. Those pages return nearly empty text, which is correct — there is no text on them — and they still count as a page if the OCR ran. If you want to save quota, remove blank pages before you upload the batch.
What Accuracy to Expect From a Scanned Document
A clean, modern scan reads at 97 to 99 percent character accuracy, which is a few wrong letters per page. An older scan — a photocopy of a photocopy, a book scanned on a flatbed in 2005 — reads at 90 to 95 percent, which is a wrong word every line or two. A poor scan — skewed, shadowed, low resolution — reads at 70 to 85 percent, and needs a full proofread.
| Source of the scan | Typical accuracy | Main problem |
|---|---|---|
| Modern flatbed scan, 300 DPI, clean original | 97–99% of characters | Almost none |
| Office photocopy scan | 93–97% of characters | Slight blur, uneven toner |
| Old book scan, yellowed paper | 88–95% of characters | Low contrast, foxing, bleed-through |
| Fax-quality scan, 150 DPI | 75–88% of characters | Low resolution; small text breaks up |
| Photograph of a page, not a scan | 80–93% of characters | Perspective, shadow, curved pages |
Historical documents deserve a special note. A 19th-century book scanned by the Library of Congress or the Internet Archive will read worse than a modern document, for reasons that have nothing to do with the scan quality: the typefaces are unfamiliar, the spelling is old, and the paper shows through from the other side. Expect 85 to 95 percent on a good historical scan, and treat the text as a searchable index rather than a finished transcription. That is how the big digitization programs use it: the OCR text makes a million pages searchable, even though no single page is perfect.
Putting the Text Back Together
OCR gives you one text file per page, and the job is not finished until those files are assembled into something readable. The simplest assembly is to concatenate the text files in order into a single document, with a page break or a page-number marker between them. If you exported DOCX, each file is a separate document, and you will need to merge them — most word processors can insert one document into another, or you can paste the text files together in order.
Reading order is the thing to check during assembly. Most pages read top to bottom, left to right, and the text comes back in that order. But a page with two columns, a sidebar, or a footnote can come back with the columns interleaved, and a page with a table can come back with the columns merged into single lines. These are layout errors, and they are visible as soon as you read the assembled text: sentences that change subject halfway through are the tell. Fix them by re-converting the problem pages with a tighter crop — one column at a time — and replacing those pages in the assembled document.
Headers, footers, and page numbers are a smaller annoyance. A scanned book repeats the running head and the page number on every page, and OCR faithfully reproduces them, so the assembled text has the same header every page. If you are publishing or quoting the text, strip those lines out. If you are only searching it, leave them: they do no harm, and they help you find which page a passage came from.
Making a Searchable PDF
The most useful single output for a scanned document is a searchable PDF: the original page images with a hidden text layer, so you can search the document and copy text from it, while still seeing the original pages. SnapText's searchable PDF export does exactly this for each page image: the image is embedded, and the recognized words are placed invisibly at their positions on the page, so a search finds them and a copy takes the text.
To make a searchable PDF of the whole document, convert the pages with the PDF export selected, then merge the per-page PDFs into one file. Free tools such as PDFsam, or the pdfunite command on Linux and macOS, merge PDFs in order. The result is a document that looks identical to the original scan and behaves like a real document: searchable, selectable, and readable by screen readers. That last point matters: accessibility standards from the W3C expect documents to contain real text, and a searchable PDF is how a scanned document meets that expectation.
If you only need the text, skip the PDF and use the TXT files. But if you are filing the document away, or sharing it with someone else, the searchable PDF is the format to keep, because it carries both the evidence — the image — and the usable text.
The Short Version
A scanned PDF is a stack of pictures, and converting it to text means OCRing every page. First check whether the PDF already has text — if you can select and copy it, you are done. If not, export the pages as PNG images at 300 DPI, upload them as a batch in order, and download the text files and the searchable PDFs. Expect 97 to 99 percent accuracy on a clean modern scan, less on old or poor scans, and proofread by confidence, lowest first. Assemble the pages in order, strip the repeated headers if you are publishing, and keep the searchable PDF as the filed copy — it is the original and the text in one file.
References
- Library of Congress, Digitization and OCR for historic newspapers: https://www.loc.gov/
- Internet Archive, Digitization and full-text search: https://archive.org/
- U.S. National Archives, Digitization programs: https://www.archives.gov/
- Tesseract OCR, official documentation: https://tesseract-ocr.github.io/
- W3C Web Accessibility Initiative, Web Content Accessibility Guidelines (WCAG): https://www.w3.org/WAI/standards-guidelines/wcag/