How to Convert an Image to Text (and Why Each Step Matters)
You have a picture with words in it — a screenshot, a scan, a photo of a whiteboard — and you need those words as text you can edit, search, or paste into a document. Retyping works, but it is slow and error-prone, and it gets worse with every page. Converting the image to text with OCR takes seconds, and the result is usually good enough to use with a quick proofread.
This guide walks through the whole job, step by step: preparing the image, choosing the right tool and settings, running the conversion, checking the result, and exporting it in a format you can actually use. The steps work with any OCR tool, but the examples use SnapText, because that is what we built — the image to text converter on the home page follows exactly this flow. If you are not sure what OCR is in the first place, start with what OCR is and how it works and come back here.
Step 1: Start With the Best Image You Can Get
OCR accuracy is decided before the software runs. The single biggest factor is the quality of the image, and the single biggest improvement you can make costs nothing: take a better picture, or use a better scan. The guide on how to improve OCR accuracy goes deep on this, but the short version fits in one paragraph.
Use the highest resolution you have. Text needs roughly 300 dots per inch to read reliably, which for a normal page means an image at least 2,000 pixels wide. A 640-pixel thumbnail of a full page will read badly no matter what software you use, because the letters are only a few pixels tall and there is not enough detail left to tell an "e" from a "c". If you are photographing a page, fill the frame with the page, hold the phone steady, and make sure the light is even — a shadow across half the page is one of the most common reasons for a bad result.
Straighten the image if you can. A page photographed at an angle distorts the letters, and most OCR engines cope badly with more than a few degrees of skew. Many phone camera apps now detect document edges and straighten the shot automatically; use that feature when it is offered. If you are scanning, feed the page straight and check that the scanner lid is closed properly, so no light leaks in at the edges.
Crop out everything that is not text. Borders, desk surfaces, fingers holding the page, and the next page peeking in from the side all confuse layout analysis, the stage where the software decides what order to read things in. A tight crop around the text block is worth thirty seconds of your time, and it pays for itself in accuracy.
Finally, check the format. JPG, PNG, and WebP are all fine. If the image is a screenshot, PNG is usually the best choice because it keeps sharp edges; JPG compression softens edges slightly, which matters for small text. If you have a scan saved as a PDF, you need to turn each page into an image first — most PDF readers can export pages as images, and our guide on converting scanned PDF pages to text covers that step.
Step 2: Choose the Right Tool for the Job
Not every image-to-text job is the same, and the right tool depends on what you are converting. Three questions decide it.
First, how many images do you have? One receipt is a different job from a folder of two hundred scanned letters. Free online tools usually limit you to one image at a time; SnapText's free plan does the same, while Starter takes 50 images per batch and Pro takes 200. If you have a batch, do not convert it one file at a time — you will spend the afternoon clicking. Upload the whole batch, let it run, and proofread the report at the end.
Second, what do you need the result for? If you only need to copy a sentence into a chat message, plain text is enough. If you need an editable document, you want a DOCX export. If you are archiving — a contract, a certificate, a set of minutes — a searchable PDF is the right format, because it keeps the original image and adds a text layer you can search later. If you are building a pipeline or feeding text into another program, JSON with word positions and confidence is the format to ask for. SnapText gives TXT on every plan and DOCX, searchable PDF, and JSON on paid plans; the pricing page lists exactly which plan includes what.
Third, how hard is the image? Clean printed text is easy for any tool. A blurry photo, a handwritten note, or a receipt printed on thermal paper that has faded is hard, and that is where the difference between tools shows. A tool that only runs Tesseract will return nearly empty text on a hard page and leave you to guess why. A tool with a second pass — a vision-model re-read for pages where the first pass collapses — can often rescue those pages. SnapText runs that re-read automatically on paid plans when Tesseract returns fewer than 20 characters or under 40 percent mean confidence.
Privacy is the fourth question, and it should be asked before the other three. Your image may contain personal information: a name, an address, a bank balance, a medical detail. Before you upload it anywhere, check what the tool does with your files. Ours are processed on our own server, never shared, never used to train models, and deleted automatically after 72 hours. Any tool you use should be able to say the same thing in plain words on its privacy page.
Step 3: Pick the Language and the Export Format
Most converters default to English, and if your image is in English, leave it there. If the text is in another language, tell the tool — OCR engines load a different language model for each language, and running English settings on a Spanish page produces noticeably worse results. SnapText offers Spanish, French, German, Portuguese, Italian, Dutch, Chinese (Simplified), Japanese, and Arabic, plus a mixed English-plus-Spanish mode for pages that switch between the two, which is common on forms and packaging in the United States.
Mixed-language pages deserve a warning. A page that is mostly English with a few Spanish words will read best with the English model and a little tolerance for the odd word; switching to the mixed mode costs a little accuracy on the English and gains a lot on the Spanish. If the page is genuinely half and half, use the mixed mode. The guide on multi-language OCR explains the trade-offs in detail.
For the export format, the rule is simple: pick the format that matches what you will do next. Copying into an email or a chat? TXT. Editing in Word or Google Docs? DOCX. Filing away for later search? Searchable PDF. Feeding another program? JSON. Choosing more formats does not cost extra pages — SnapText counts one image as one page no matter how many formats you export — so there is no reason to be stingy. Pick every format you might need, and ignore the rest later.
Step 4: Upload and Convert
The mechanics are the same on almost every converter. On SnapText, drag the images onto the home page or click to choose them, check the list of files, pick the language and formats, and press convert. A guest can convert without an account; registering is free and gives you a history of your conversions, so you can come back to a result later instead of converting the same image twice.
While the job runs, each image is read in turn. A clean page takes a few seconds. A batch of fifty takes a few minutes, and you will get an email when it finishes if you left an address. Do not close the tab and assume the job died — the work happens on the server, and the page polls for the result. If a single image in a batch fails, the rest still complete, and the report tells you which one failed and why, instead of failing the whole batch silently.
One practical detail matters here: quota is counted per successful page. A failed image never counts against your monthly allowance, and neither does an image that turns out to be corrupt. If you hit your monthly limit halfway through a batch, the upload is refused before anything is processed, with a message telling you how many pages you have left and what upgrading would give you. That is better than a tool that accepts the batch, processes half of it, and then stops.
Step 5: Check the Result Before You Trust It
| Mean confidence | What it means | How to proofread |
|---|---|---|
| Above 90% | Clean read | Skim; check numbers |
| 70–90% | Good, with errors | Read the flagged words, then skim the rest |
| 40–70% | Struggling | Read the whole page against the image |
| Below 40% | Collapsed or re-read | Treat as a draft; consider a better photo |
This is the step most people skip, and it is the step that matters most. OCR is not perfect, and the errors it makes are exactly the kind a quick skim will miss: a "1" read as a lowercase "l", a "0" read as an "O", a decimal point dropped from a total. Always proofread the result against the original image, at least for the parts that matter — names, numbers, dates, totals.
The confidence report exists to make this fast. On SnapText, every page shows a mean confidence percentage, and every word below 60 percent confidence is listed for you. Start there. Read the flagged words against the image and fix them; the rest of the page is usually right. If the mean confidence is above 90 percent, a light skim is enough. If it is below 70, read the whole page carefully. If it is below 40, the page was probably re-read by the vision model already (on paid plans), and you should treat the whole result as a draft, not a finished transcription.
Two specific checks catch most real errors. First, numbers: compare every number in the result against the image, digit by digit. OCR confuses digits more than letters, and a wrong number in an invoice or a receipt is the error with real consequences. Second, names: proper names do not appear in dictionaries, so the language model cannot correct them, and a misread surname will sail through unnoticed unless you check it.
If the result is badly wrong — whole paragraphs missing, or text in the wrong order — the problem is usually the image, not the engine. Check whether the page was skewed, shadowed, or too low in resolution, fix the image, and convert it again. Converting the same image twice costs one more page of quota, but a second conversion of a better image is worth far more than an hour spent fixing a bad transcription by hand.
Step 6: Export, Save, and File the Result
Once the text looks right, download it. SnapText bundles the whole job into one ZIP file with the exported text files and a CSV report listing every page, its confidence, and its status. Keep that report: if you come back to the text in six months and find a strange word, the report tells you whether that page was a confident read or a guess.
Name your files sensibly at this point. A file called "IMG_4521.txt" tells you nothing in a year's time; "2026-11-08-receipt-coffee-house.txt" tells you everything. If you exported a searchable PDF, file it where you file the original — it replaces the scan for most purposes, because it contains both the image and the text.
Remember the retention window: files are kept for 72 hours and then deleted automatically. Download what you need within that window. If you registered, your conversion history lists your past jobs, but the files themselves still expire after 72 hours, so download first and organize later.
What to Do When a Page Will Not Convert
Sometimes a page comes back empty, or nearly empty, even though you can read it perfectly well yourself. Work through the causes in order. Is the image actually an image? A PDF uploaded as a file, or a Word document renamed to .jpg, will be rejected — the tool reads image files, not documents. Is the text too small? Zoom in: if the letters are under about 10 pixels tall, enlarge the image or re-scan at a higher resolution. Is the page upside down or sideways? Rotate it before uploading; OCR engines assume the text runs left to right and will return garbage from a rotated page. Is it handwriting? Joined-up cursive defeats most engines — see handwriting to text for what to expect and how to improve it.
If none of those apply and the page still fails on a paid plan, the vision-model re-read has probably already run and also struggled. That usually means the image itself is the problem: extreme blur, very low contrast, or text printed over a busy background. Re-photograph the page in better light, straight on, and try again — a new photo is almost always faster than fighting with the old one.
The Short Version
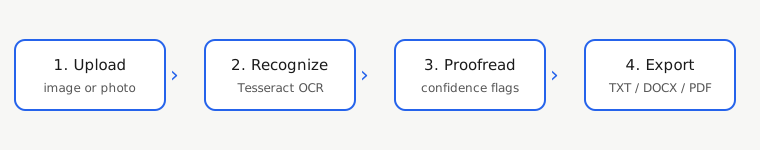
Convert an image to text in six steps: get the best image you can, pick a tool that fits the batch size and the privacy you need, set the language and export format, upload, proofread against the confidence report, and download within 72 hours. The conversion itself takes seconds; the proofreading is where the quality comes from. And when a page comes back wrong, fix the image and convert again — that is almost always faster than fixing the text by hand.
References
- Tesseract OCR, official documentation: https://tesseract-ocr.github.io/
- Library of Congress, Digitization and OCR for historic newspapers: https://www.loc.gov/
- U.S. National Archives, Digitization programs: https://www.archives.gov/
- W3C Web Accessibility Initiative, guidance on text alternatives and document accessibility: https://www.w3.org/WAI/
- National Institute of Standards and Technology (NIST), document and handwriting recognition research: https://www.nist.gov/