What Is OCR? How Image to Text Conversion Works in Plain Words
You have a photo of a page, a screenshot of an error message, or a scan of a contract. The words are right there — you can read them — but your computer cannot. It sees a grid of colored dots, not letters. OCR is the technology that bridges that gap: it looks at a picture, finds the letters in it, and hands you back real text you can copy, search, and edit.
This guide explains what OCR is, how it works, where it is used, and what it can and cannot do. When you are ready to try it, the image to text converter on the home page turns a picture into editable text in seconds, and the companion guide on how to convert an image to text walks through the steps.
What OCR Means
OCR stands for Optical Character Recognition. The name is older than the technology most people meet today: it was first used for machines that read printed characters in the 1950s and 1960s, when banks and postal services needed to sort cheques and letters automatically. The early systems could only read one specially designed font, and they needed the paper fed through in exactly the right position. Modern OCR is the same idea grown up: software that reads almost any printed text, in many languages, from a photo taken at an angle on a phone.
The key idea is that text in an image and text in a document are different things. A Word document stores the letter "A" as a code that means the letter A. A photograph of the letter A stores thousands of pixels, some dark and some light, arranged in the shape of an A. Nothing in the file says "this is a letter." OCR is the process of deciding, from the shape of the dark pixels, which letter each shape is — and then writing out those letters as real text.
That distinction matters in everyday life more than most people realize. A scanned contract you receive by email is usually a picture of text, not text. You cannot search it, you cannot copy a paragraph out of it, and a screen reader cannot read it aloud to a blind colleague. After OCR, all of those things work, because the file now contains the words themselves. This is why libraries, archives, and government offices have spent decades scanning and OCRing their collections: the Library of Congress has digitized millions of pages, and its Chronicling America project makes historic newspapers searchable precisely because OCR turned pictures of pages into text.
How OCR Works, Step by Step
An OCR program works through a picture in stages, and each stage answers one question. The first question is: where is the text? Before a single letter can be read, the software has to find the blocks of text on the page, separate them from pictures and diagrams, and work out the order they should be read in. A two-column newspaper article, for example, must be read down the left column and then down the right one — reading straight across both columns would mix the sentences together. This stage is called layout analysis, and it is one of the reasons a clean, straight scan reads far better than a tilted photograph of a page taken at an angle.
The second question is: where does each character start and end? The software looks at each line of text and cuts it into individual characters, a step called segmentation. Printed text in a normal font segments cleanly, because the letters stand apart from each other. Cursive handwriting is hard exactly here: the letters join together, so the program cannot tell where one ends and the next begins. This is the main reason handwriting recognition lags behind printed-text recognition, and it is why our guide on handwriting to text sets expectations carefully instead of promising perfection.
The third question is: what letter is this shape? The classic answer is pattern matching — compare the shape against stored examples of every letter and pick the closest match. Modern systems, including the Tesseract engine that powers SnapText, use a trained neural network instead. The network has been shown millions of examples of letters in many fonts, sizes, and conditions, and it has learned which features distinguish an "e" from a "c", or a "1" from a lowercase "l". Neural networks are far better at coping with real-world mess: slightly blurry text, unusual fonts, and uneven lighting.
The fourth and final stage is the one most people never see: the software uses language to fix its own mistakes. If it reads "teh" in the middle of an English sentence, a built-in language model knows that "the" is far more likely, and corrects it. If it reads a word that does not exist in the dictionary, it reconsiders the second-best guess for each letter. This is why OCR is noticeably better on ordinary prose than on random strings of characters, and why a page of part numbers or passwords — text with no language pattern to lean on — is read less accurately than a paragraph of normal English.
Why OCR Accuracy Is Never 100 Percent
No OCR system reads perfectly, and any tool that promises 100 percent accuracy is overselling. The honest question is not whether errors happen, but how often, and whether you can find them. On a clean scan of printed text, a good engine reads 98 to 99 percent of characters correctly. That sounds excellent until you count what it means: a 500-word page contains roughly 3,000 characters, so 1 percent wrong is about 30 wrong characters — a few wrong letters on every page. On a blurry phone photo, the error rate can be ten times higher.
Several things move the number.
| Source | Typical character accuracy | Main factor |
|---|---|---|
| Clean scan of printed text | 98–99% | High resolution, even light |
| Screenshot of typed text | 97–99% | Perfect contrast, no blur |
| Phone photo of a page | 88–95% | Angle, shadow, and focus |
| Receipt on thermal paper | 80–90% | Small print, faded ink |
| Neat handwriting | 70–90% | Letter shapes vary by writer |
| Joined-up cursive | 60–80% | Letters merge; segmentation fails |
Resolution is the biggest: text smaller than about 10 pixels tall per character starts to fall apart, because there are not enough pixels left to tell letters apart. Skew is next: a page photographed at an angle distorts the letter shapes. Contrast matters too: pale grey text on a white background, or a photo taken in dim light, leaves the software guessing where the letters end and the background begins. And language matters: English reads best, because the language models are trained on the most data, while scripts the engine has seen less often read worse.
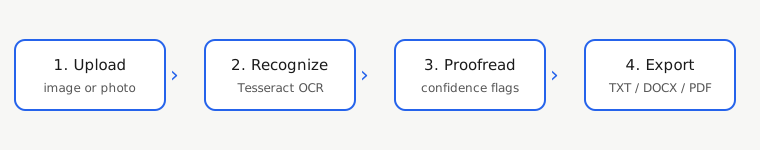
This is why SnapText shows a confidence score for every page and flags the individual words it is unsure about. A confidence report does not make the errors go away, but it changes the job from "re-read the whole page" to "check these twelve words," which is a much smaller job. The guide on how to improve OCR accuracy explains the practical steps — better lighting, straighter photos, higher resolution — that move the number the most.
Where OCR Is Used Every Day
OCR is one of those technologies that disappears into the background once it works. When you deposit a cheque by photographing it, OCR reads the amount and the account number. When you scan a receipt for expenses, OCR pulls out the total and the date — our guide on converting receipts to text covers that case in detail. When a delivery driver scans a parcel label, OCR reads the address. When your phone offers to copy text out of a photo in your camera roll, that is OCR running on the device.
In offices, the biggest use is turning paper archives into searchable files. A law firm with forty years of contracts in filing cabinets cannot search them until every page has been scanned and OCRed. A hospital digitizing patient records faces the same problem. Government archives are the largest example: the U.S. National Archives holds billions of pages, and digitization programs OCR them so that a researcher can find a single name in a collection that would otherwise take a lifetime to read by hand.
Accessibility is the use that matters most and gets talked about least. A blind person using a screen reader cannot read a scanned PDF that is only a picture of text — the screen reader finds nothing to read. OCR gives the document a real text layer, and the same file becomes readable aloud. This is a legal requirement in many contexts as well: accessibility standards such as the Web Content Accessibility Guidelines from the W3C expect documents to contain real text, not pictures of text. If you publish a scanned document, running OCR on it is not a nice extra; it is part of making the document usable by everyone.
OCR, AI Vision Models, and the Difference
In the last few years a second way to read text from images has appeared: large vision models — the same kind of AI that can describe a photograph — can also transcribe the text in it. These models are often better than classic OCR on the hardest pages: crooked photos, handwriting, decorative fonts, and pages where the text wraps around pictures. They are also slower and more expensive to run, which is why most tools do not use them for every page.
SnapText uses both, in layers. Tesseract reads every page first, because it is fast and free to run. If a page comes back nearly empty, or with very low confidence, a vision model re-reads that page — Mistral-large first, with a second model as a fallback — but only on paid plans, and only for pages that need it. Pages that Tesseract reads well never touch the vision model at all. This layered approach is the same idea the industry has settled on: use the cheap, fast tool for the easy 95 percent, and spend the expensive tool only where it changes the result.
What OCR Cannot Do
Honest limits are worth stating plainly. OCR cannot read text that a human cannot read either: if the photo is so blurry that you cannot make out the words, no software will do better than guessing. It cannot reliably read handwriting that joins letters together, decorative script fonts, or text printed over a busy photograph. It cannot understand the document — it can tell you that a page says "Total: $45.00", but it does not know what was bought, and it will not check the arithmetic. And it cannot recover text that was never in the picture: a folded corner hides the words underneath it, and no amount of processing brings them back.
There are also privacy limits worth knowing. A photo of a document is still the document. If you OCR a page containing personal information — a medical record, a bank statement, a passport — the resulting text contains that same information. SnapText deletes uploads and results automatically after 72 hours and never uses your files to train models, but the general rule stands: do not upload documents you would not want anyone else to see, and check what a tool does with your files before you trust it with sensitive pages.
How to Judge an OCR Tool
If you are choosing between OCR tools, four questions separate the good ones from the rest. First, does it show you confidence? A tool that reports a single block of text with no indication of what it is unsure about is asking you to proofread everything. Second, does it handle batches? Converting one image at a time is fine for a single receipt, but a drawer full of paper needs a tool that takes fifty or two hundred images in one go. Third, what can you export? Plain text is enough for a quote, but a Word document you can edit, or a searchable PDF that keeps the original image, is worth paying for. Fourth, what happens to your files? A serious tool states its retention period in plain words — ours is 72 hours, automatic — and does not train models on your documents.
The free plan on SnapText answers the first question for every page: every result carries per-word confidence, and uncertain words are flagged. Paid plans add the batch sizes, the vision-model re-read, and the DOCX and searchable PDF exports. The pricing page lays out the exact numbers.
The Short Version
OCR turns pictures of words into real words. It works in four stages — find the text, cut it into characters, recognize each character, and use language to fix mistakes — and it is very good on clean printed text, decent on photos, and honest-to-goodness limited on handwriting and blur. It powers cheque deposits, receipt scanning, archive search, and screen readers. It is never perfect, which is why a confidence report matters more than a bold accuracy claim. And when the first pass fails, a second look from a vision model can often save the page.
If you have an image in front of you right now, the fastest way to understand OCR is to try it: upload the image on the home page, read the confidence score, and check the flagged words against the original. That single experiment will teach you more about what OCR can do than any guide — including this one.
References
- Library of Congress, Chronicling America — historic newspaper digitization and searchable text: https://www.loc.gov/
- U.S. National Archives, Digitization programs: https://www.archives.gov/
- Tesseract OCR, official documentation: https://tesseract-ocr.github.io/
- National Institute of Standards and Technology (NIST), handwriting and document recognition research: https://www.nist.gov/
- W3C Web Accessibility Initiative, Web Content Accessibility Guidelines (WCAG): https://www.w3.org/WAI/standards-guidelines/wcag/